A mobile app can work perfectly in a demo environment and still encounter problems in real-world use. Payments may fail when an internet connection drops, forms may lose data if a user switches apps, and buttons may become unresponsive, leading users to tap them repeatedly.
These issues can be easy to miss during testing under ideal conditions. They can affect user trust, task completion, and continued app usage.
Mobile apps operate in environments where network conditions, device capabilities, and user activity can vary. Although developers cannot control every aspect of the environment, they can account for these variations through thoughtful architecture, testing, supported-device policies, and appropriate fallback behavior.
That is why successful mobile app development involves more than delivering features and creating an attractive interface. It requires decisions about how the application behaves when connectivity disappears, a workflow is interrupted, a request fails, or a device struggles to perform.
These considerations should influence architecture, UX, testing, and maintenance from the beginning. When reliability is treated as a product and engineering requirement rather than a final quality check, the application is better prepared for the conditions users actually encounter.
Mobile users will not always have a reliable internet connection. They may be in an area with poor coverage, moving between Wi-Fi and cellular networks, or using the application inside a building where signal quality is inconsistent.
Even a brief interruption can have an effect on an app that is entirely server-dependent. The screen could be left hanging on a loading indicator, the request could time out, or the user could be left in the position of wondering whether their data has actually been saved at all.
The solution is not necessarily to make every app fully functional offline. The important thing is to understand which features require a live connection and what the app should do when that connection is unavailable.
Different applications have different connectivity requirements. A news application may allow users to read previously downloaded articles without an internet connection. A productivity application may need to preserve drafts and let users continue editing. A financial application may allow users to view cached information while demanding a secure server connection to authorize transactions.
These differences should be kept in mind during product planning.
For workflows that can continue safely offline, the application can persist the necessary information on the device using storage appropriate to the type and sensitivity of the data. When connectivity returns, pending changes can then be synchronized with the server.
However, offline support introduces its own design challenges. Users need to know what data is available offline, whether their most recent changes have been saved, and whether those changes have reached the server.
A good interface should be able to tell the difference between a draft that’s been saved on the device, an update that’s been made but is still pending sync, and an update that’s been accepted by the server. Without that distinction, the user is left in the dark as to whether or not their changes have actually been submitted.
Offline support is only as reliable as the process used to synchronize information later.
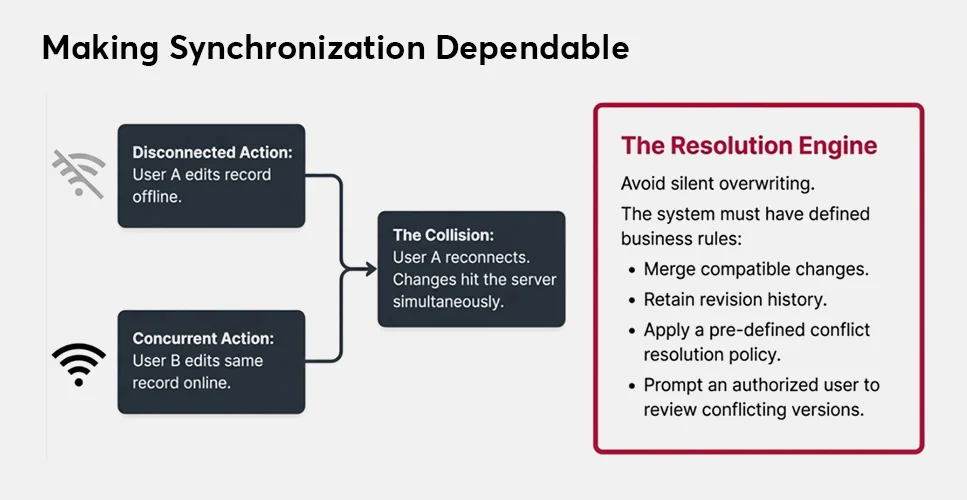
Consider a user who edits a record while offline. Before the device reconnects, another user updates the same record through a different device. When both changes reach the server, the application needs a defined way to handle the conflict.
Depending on the data and the business rules, the system could merge the compatible changes, retain the revision history, apply a pre-defined conflict resolution policy, or ask an authorized user to review the conflicting versions.
Silent overwriting can lead to inconsistencies that are difficult to track down later.
Synchronization also needs to handle interrupted uploads, expired authentication, duplicate requests, and temporary server errors. Pending changes should not disappear simply because the app closes or the network connection drops while an upload is in progress.
Developers should test these scenarios rather than assume synchronization will succeed whenever connectivity returns.
Retrying a failed request can improve the user experience, but retries must be designed around the type of operation being performed.
If an app asks for a list of articles and that request fails, then retrying is pretty straightforward. A payment or booking request is a different matter. The server may have in fact completed the operation even though the response never made it back to the device.
If the app re-sends the same request without some appropriate safeguards, then you could end up with a duplicate transaction or booking.
For operations that must not be processed more than once, developers can use techniques such as idempotency keys, request identifiers, and server-side duplicate detection. The appropriate implementation depends on the operation and the systems involved.
The user interface should also communicate what is happening. Rather than leaving someone guessing, it should explain when an action is being processed, when it has failed, and what the user can safely do next.
Reliable connectivity handling is not about hiding every network problem. It concerns ensuring that temporary interruptions do not unnecessarily lead to lost work, inconsistent records, or confusion.
People don’t typically use mobile apps in isolation. A phone call could come in and interrupt a form, a notification could pull your attention away from whatever you’re doing, or you might just switch to another app to look something up.
The OS may also suspend an app, reclaim memory, or terminate a process under certain circumstances.
If an application assumes that users will complete every task without interruption, it risks losing information and forcing people to repeat work.
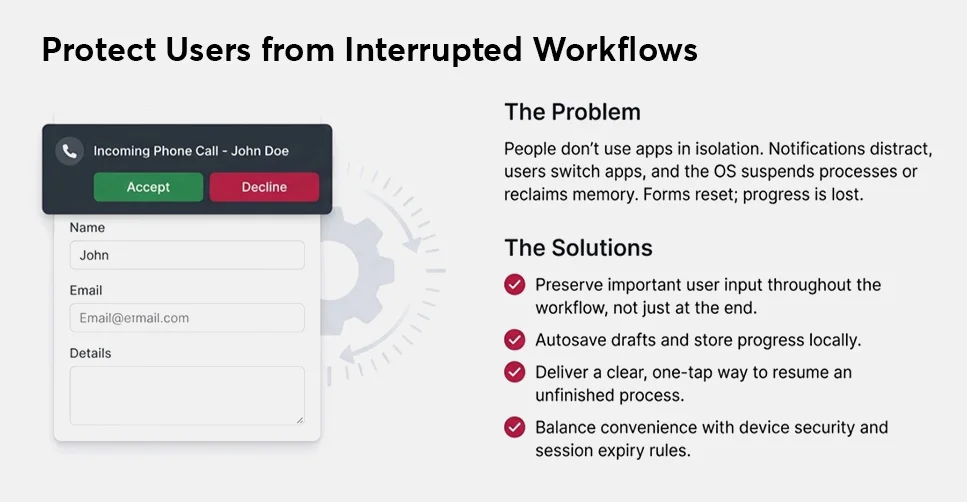
Imagine someone filling out a long application form. They complete several sections, then switch to another application to check a reference number. When they return, the form has reset.
Even if the information can be entered again, the experience creates unnecessary effort and reduces confidence in the product.
Applications should preserve important user input at appropriate points throughout a workflow. Depending on the task, this may include autosaving drafts, storing progress locally, restoring the previous screen, or delivering a clear way to resume an unfinished process.
Developers also need to think about when the information is saved. It may not be appropriate to wait until the end of the form, particularly in the case of long forms or workflows where the loss of progress would be a serious issue.
At the same time, sensitive information should not be stored locally without appropriate protection. Data retention, session expiry, and device security all need to be considered in the same breath as convenience.
The aim is to make recovery part of the normal user experience rather than an afterthought.
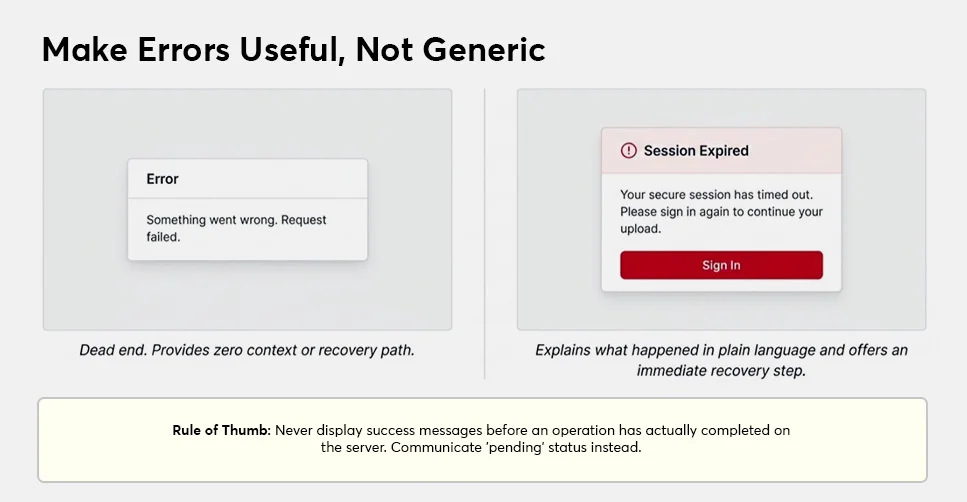
An error message should help the user understand what has happened and what they can do about it.
Generic messages such as “Something went wrong” or “Request failed” provide little useful context. When possible, an error message should explain what happened in plain language and tell the user what they can do next.
For example, if a session has expired, the application can explain that the user has to sign in again. If a file upload fails because the connection was interrupted, it can offer a retry option while preserving the selected file.
Not every error can be explained in detail, and technical information should not be exposed where it could create security risks. The important distinction is between reporting that something failed and helping the user recover from the failure.
Applications should also avoid displaying success messages before an operation has actually completed. If an action is still being processed by the server, the interface should communicate that status rather than imply that the result is confirmed.
Repeated taps can occur when an app appears unresponsive. Without clear feedback that an action is being processed, users may tap a submission button multiple times.
Temporarily disabling the button, displaying a loading state, and providing confirmation can help prevent duplicate actions at the interface level.
However, interface controls alone are not sufficient for operations with significant consequences. Network delays and repeated requests can still occur outside the expected interaction pattern.
The server should have appropriate safeguards in place for operations such as payments, bookings, account changes, etc., where it would be problematic to have a duplicate transaction.
A robust workflow should also make the result easy to verify. The user should be able to see whether their request has succeeded, failed, or is still pending.
Designing for interruptions and recovery helps reduce repeated work, duplicate actions, and uncertainty about whether an operation succeeded.
Mobile applications operate across several screen sizes, operating system versions, system capabilities, and accessibility settings. An interface that works well on one device may be difficult to use on another.
Device compatibility is therefore about more than making sure that an application installs successfully. It also involves making sure its core workflows remain usable and dependable across the devices and environments the product supports.
Layouts should be responsive and adapt to different screen sizes without the risk of hiding the essential information or making the common actions hard to find.
Text should be readable, the buttons should have appropriate touch targets, and navigation should be consistent enough for the user to know where they are in the app.
Performance will also vary from device to device. An older phone or one with limited memory may well struggle with large images, complex animations, or heavy background processing.
Teams can address these differences by optimizing images and other assets, loading content efficiently, limiting unnecessary background work, and testing on representative devices.
The right balance depends on the application. A media-intensive app will have different performance requirements from a simple utility, but in either case, essential functionality must remain reliable across supported devices.
Accessibility should be considered throughout design and development rather than added only after the interface has been completed.
Users may rely on screen readers, larger text, sufficient color contrast, captions, or alternative ways to use an interface. Applications should be designed so that important information and actions remain available when these features are enabled.
A button that communicates its purpose solely through color may be difficult for some users to understand. A control without a meaningful accessibility label may also be confusing when accessed through a screen reader.
Testing with accessibility tools and, where possible, users with different needs can help identify issues that a visual inspection might miss.
Accessible design can also improve usability more broadly. Clear labels, predictable navigation, readable content, and understandable error messages benefit a wide range of users.
The environment in which someone uses an application can affect how easily they complete a task.
Users may be moving between locations, dealing with interruptions, operating with one hand, or relying on a device with limited battery power. An application should make common actions simple without presuming ideal conditions.
This entails prioritizing important information, lessening unnecessary steps, preserving progress, and avoiding interfaces that depend on exact interactions when simpler alternatives are possible.
It also means testing on actual devices instead of relying exclusively on emulators or the newest available hardware.
The aim is not to support every conceivable device and scenario. The aim is to identify the scenarios that actually matter to the user and build the app to deal with those reliably.
Most applications are initially tested against expected user journeys. A user opens the app, signs in, selects a feature, submits information, and receives the expected result.
These tests are necessary, but they do not reveal how an application behaves when something goes wrong.
Real users encounter expired sessions, slow responses, interrupted uploads, unexpected inputs, changed permissions, and network issues. These situations need to be considered as part of the testing process.
A useful testing strategy examines not only whether a feature works, but also whether users can recover when it does not.
Depending on the application, test scenarios might include:
These scenarios help reveal whether the application preserves information, communicates status accurately, and avoids processing the same action incorrectly.
Testing should also verify what happens after recovery. An application may appear to resume successfully while leaving an incomplete record or an inconsistent state behind.
Mobile applications often depend on authentication services, APIs, databases, payment providers, analytics tools, and other external systems.
A failure in one of these services can affect the entire user journey.
Testing should therefore include scenarios in which a service is unavailable, returns an unexpected response, or takes longer than expected. The application should be checked to ensure it does not crash or present misleading information under these circumstances.
Integration tests can verify that connected components exchange information correctly and handle expected failure conditions. Automated tests can exercise repeatable scenarios consistently, while manual testing can uncover usability problems and unexpected behavior.
Both are important because a technically correct response does not necessarily produce a clear or usable experience for the person using the application.
Testing only on a high-performance device connected to a fast network can leave important problems undiscovered.
Teams should select devices and OS versions based on the target audience and supported environment. Testing should cover representative network conditions, screen sizes, memory constraints, and accessibility settings.
The goal is not to test every possible combination. It is to identify the conditions most likely to affect users and prioritize those risks.
Testing should continue as the app develops. Any change to authentication, sync, or navigation could have an impact on workflows that were previously working correctly. Regression testing is therefore a key part of the ongoing development process.
A well-tested application is not one expected to avoid every failure. It is one whose critical workflows, failure modes, and recovery paths have been deliberately exercised.
Launching an application does not mean every failure mode has been anticipated. OS updates, changing dependencies, new devices, evolving usage patterns, and real-world conditions can expose issues that did not appear during development. Teams therefore need a way to understand application behavior after release and decide which improvements deserve attention.
Teams need a plan to understand how the application performs after release and decide which improvements deserve attention.
Crash reports can help identify where an application fails and which versions or devices are affected. Performance monitoring can reveal slow screens, delayed requests, and operations that consume too many resources.
These signals become more useful when they are connected to the user journey. A crash affecting sign-in or payment processing may have a different impact from one affecting a rarely used feature.
Monitoring should also consider failed requests, synchronization delays, repeated retries, and errors returned by integrated services.
The purpose is to identify meaningful problems, understand their causes, and prioritize fixes according to their impact on users.
Usage metrics can disclose patterns, but they do not always explain why users behave in a particular way.
If users repeatedly abandon a form, the cause may be a technical failure, unclear instructions, excessive steps, or a missing capability. Analytics can show where friction occurs, while support requests, interviews, app reviews, and usability testing can help explain why.
These signals should be evaluated together and in the context of the application’s purpose, user needs, technical constraints, and available evidence.
Not every request has to become a feature. Feedback has to be assessed in the context of the application’s purpose, the users’ needs, the technical constraints, and the evidence available.
An application may accumulate many possible improvements after launch. Treating every issue as equally urgent can make it difficult to focus on the problems that matter most.
Teams can prioritize work by considering severity, frequency, the number of users affected, and the consequences of failure.
For example, an issue that causes data loss or prevents users from completing an important task will generally deserve attention before a minor visual inconsistency.
After making a change, teams should verify whether it resolved the original problem and check that it did not cause new issues elsewhere.
This creates a continuous improvement cycle: monitor the application, investigate problems, prioritize changes, test the solution, and review the results.
Reliability is easier to achieve when it is considered from the beginning of the mobile app development process rather than treated as a final quality check.
During planning, teams should identify the application’s most important user journeys and consider what could interrupt them. Which actions require a live connection? What information must be preserved? Which operations must not be processed twice? What should users see when a request fails?
The answers will have an impact on the architecture, the data model, the interface design, and the testing strategy.
During development, put appropriate safeguards in place for local data, synchronization, authentication, error handling, and external dependencies. The implementation will vary by product, but the principles remain consistent: protect critical data, communicate application state clearly, define recovery behavior, and avoid silent failure.
Before release, test both expected workflows and realistic failure and recovery scenarios. After launch, monitoring and user feedback should help identify where additional improvements are needed.
Not every application needs full offline capability or complex synchronization. The appropriate level of investment depends on the product, its users, the sensitivity of its data, and the consequences of failure.
These decisions should be made deliberately during planning rather than after users encounter a problem.
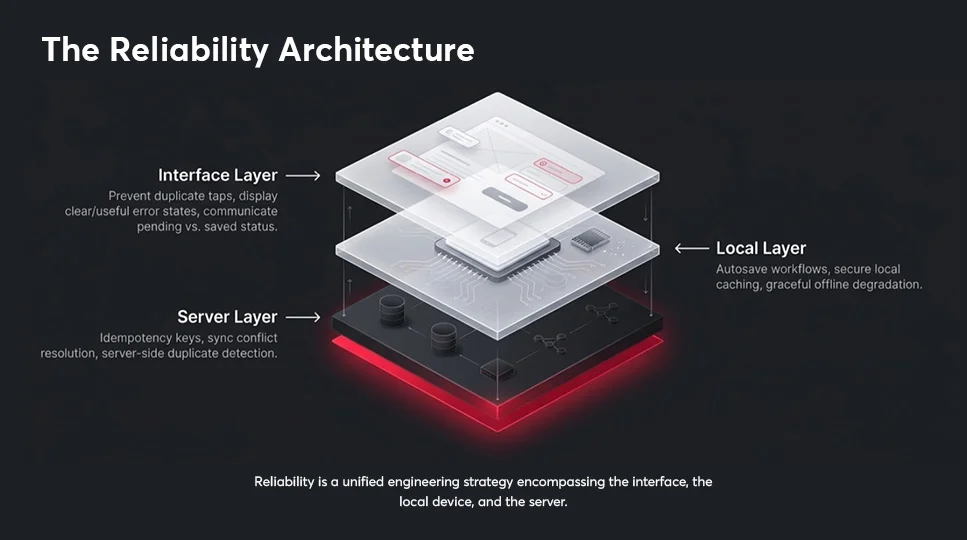
Successful mobile app development is not simply about making an application work when everything goes according to plan. It is about making sure users can complete important tasks when connectivity is unreliable, interruptions occur, devices behave differently, or a submission fails.
Offline behavior, dependable synchronization, accessible interfaces, clear error handling, realistic testing, and post-launch monitoring all contribute to a more reliable mobile experience.
For businesses building a new mobile application or modernizing an existing one, reliability should be treated as a product and engineering requirement alongside features, security, UX, and delivery timelines.
At InApp, we design and develop native and cross-platform mobile applications for iOS and Android, with backend integration, testing, and deployment aligned to business and user requirements. Building for real-world conditions from the start helps create applications that remain dependable beyond the demo environment.
Explore InApp’s mobile app development services to learn more.